_The mental model you bring to your first conversation determines whether AI becomes a daily tool or gets forgotten after the second attempt._
Overview
Two people install the same AI assistant in the same week. A month later, one uses the tool every day to organize their routine, write difficult messages, and decide what to do about an annoying problem; the other gave up after the second conversation because "it's useless for anything real." The difference is almost never the tool — it's the mental model each person brought to their first conversation. This chapter builds that mental model before any practical application, because every following chapter in this course assumes you already clearly understand what AI is and what it isn't in your daily life.
Key Concepts
An AI assistant doesn't keep a file about you or check your real life before responding. By default, it starts from a nearly blank state: it knows how to write well, structure information, and follow a line of reasoning — but it doesn't know you have two kids, that your boss is strict about deadlines, or that you hate phone calls, unless you tell it. It's an extremely competent generalist professional who just showed up on your first day at work: the competence is real, the context about your specific life is zero until you provide it.
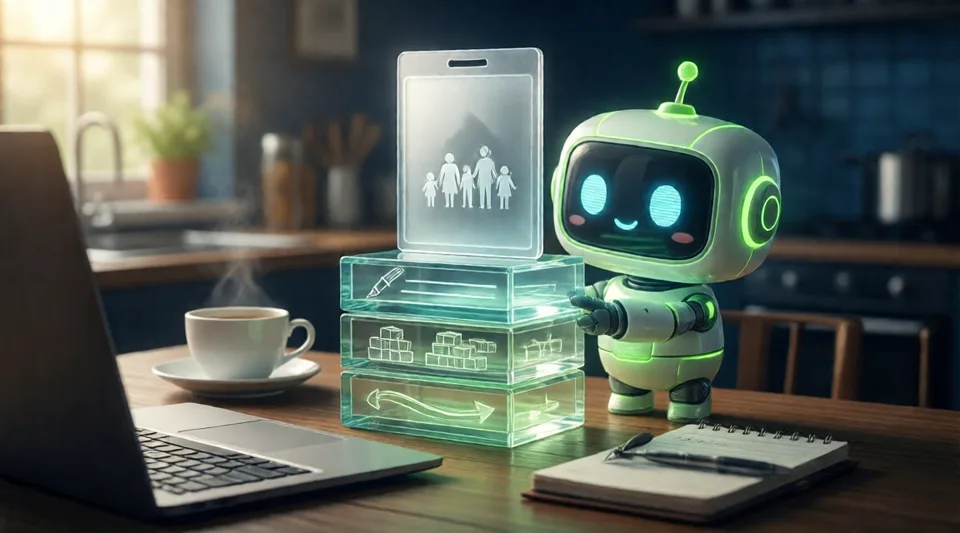
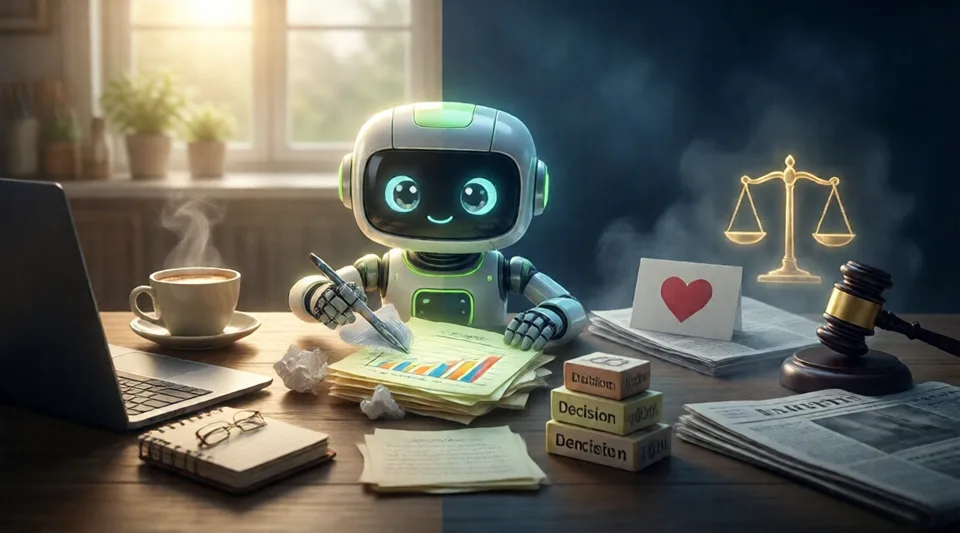
From that foundation, you can map where AI pays off most in everyday life and where it pays off least. It's strong in three areas: organizing scattered information (a loose to-do list becomes a plan), producing a first draft of any communication (an email, a message, a summary), and structuring a complex decision into smaller parts. It's weak in three others: anything that depends on recent, specific facts it has no way to confirm, anything that requires real emotional presence (nobody wants to discover the condolence message they received was 100% generated without editing), and any decision with legal, financial, or medical consequences that doesn't go through human verification.
The third concept ties the other two together: calibrate by risk. Asking what recipe to make with what's left in the fridge and asking whether a medication can be taken with alcohol are, technically, two uses of the same assistant — but the cost of a wrong answer is completely different. The greater the consequence of an error, the more verification effort you need to put in after the response, not less.
Execution Flow
- Choose a starting domain. Don't try to use AI for everything in the first week — pick a single recurring source of friction (what to cook, how to respond to annoying emails, how to organize your schedule) and start only there.
- Describe your real situation before asking for anything. Who you are in that context, what you've already tried, what's at stake — without this, the response comes out generic.
- Ask for a first version and treat it as a draft, not as a finished deliverable — the first response is a starting point, almost never the final one.
- Classify the risk of what you received. Low risk (a dinner suggestion) can be used directly; high risk (a contract interpretation) requires external verification before acting.
- Repeat in the same domain for a week before expanding to another — this builds the calibration habit before multiplying your uses.
Applied Scenarios
A common, low-risk starting scenario: coming home, opening the fridge, seeing leftovers with no clear idea what to do with them, and asking the assistant "I have yesterday's rice, half a bell pepper, three eggs, and some cheese — what can I make quickly?". A mistake here costs, at most, a bland dinner. It's exactly the kind of use ideal for building confidence in the tool without real risk.
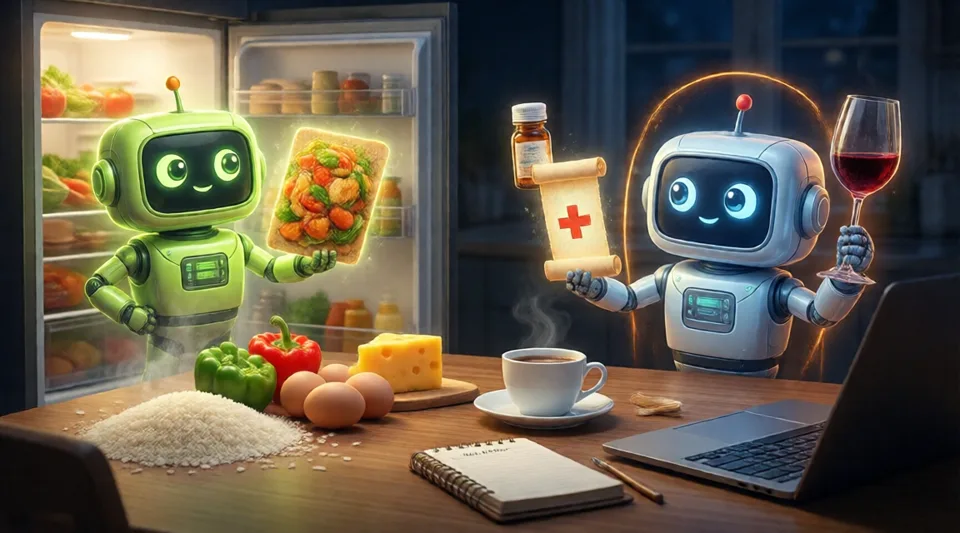
Compare that with another scenario, with much higher risk: asking whether a certain medication can be taken with alcohol before a party. The response can come with the same fluency and the same confident tone as the dinner scenario — but here, a mistake has real consequences for your health. The tool doesn't signal this risk difference on its own; calibrating for it is your job, not its. For this kind of question, the AI's response should be treated as a starting point for a search in a reliable source (package insert, pharmacist, doctor), never as a final verdict.
Common Mistakes
- Treating every response with the same level of confidence, without calibrating for the risk of the situation.
- Expecting the assistant to "already know" details about your life that were never mentioned in the conversation.
- Testing the tool only on trivial tasks and concluding it's useless for anything serious — or the opposite, testing only on serious tasks and giving up at the first mistake.
- Comparing AI behavior to a traditional search and being surprised when it produces something plausible but incorrect — they're different mechanisms under the hood.
- Confusing "AI doesn't know the answer" with "AI answered confidently but is wrong" — on the surface, the two look identical.
Pro Tip: On any topic outside your area of expertise, ask directly: "is there any chance you're wrong in this response, and in which specific part?". Models like Opus 5 tend to flag their weakest points well when asked directly — this doesn't eliminate the risk, but it shows you where to focus your verification.
Practical Exercise
Choose a recurring annoyance from your week — what to cook, what to wear considering the weather and your schedule, how to respond to an annoying email sitting in your inbox. Have three conversations with the assistant strictly within that domain over the next few days. In each one, note: what was the risk of the response (low, medium, high) and what you did to verify before acting. At the end of the week, reread your notes and identify a pattern in your own trust behavior.
Implementation Checklist
- I can explain, in my own words, why AI can answer incorrectly with a confident tone.
- I chose a specific domain in my routine to start using the tool.
- I provide context about my real situation before asking for a response.
- I classify the risk of each response before deciding how much to verify.
- I neither abandoned nor idolized the tool after a single good or bad result.
Chapter Summary
- An AI assistant starts each conversation with almost no context about you — the competence is real, the knowledge of your specific life needs to be provided.
- AI pays off most in organizing information, generating drafts, and structuring decisions; it pays off least in recent verifiable facts, real emotional presence, and high-risk decisions.
- Calibrating by the risk of the response — not by the confidence of the tone — is the central habit of this entire course.
- Testing in a single low-risk domain before expanding builds calibrated confidence, not blind confidence.
- The next chapter shows how to set up the assistant so it already arrives with context about your life, instead of starting from scratch every time.
---